On-premise
Runs on a server inside your own building. Video never leaves your network.
Simat Labs conducts research and builds highly optimized visual intelligence systems to solve real-world problems. At Simat, we understand the high cost of computation and focus our efforts at reducing it.
In the field
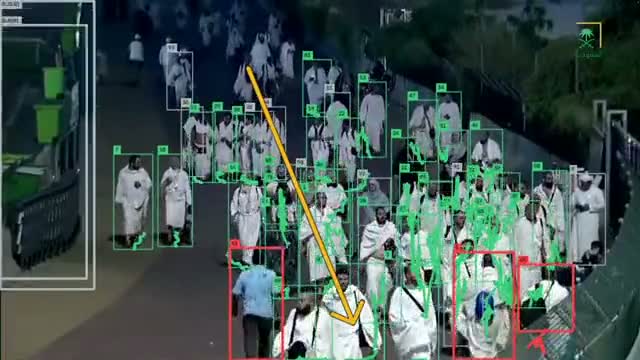
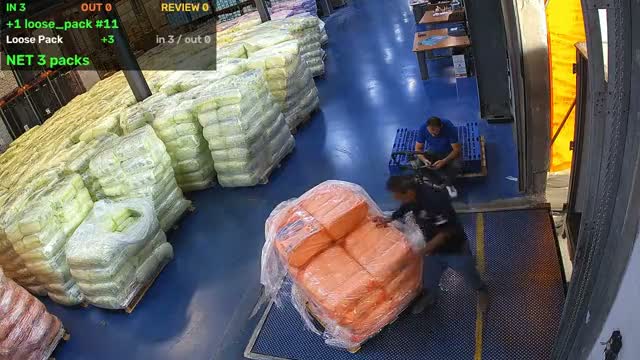
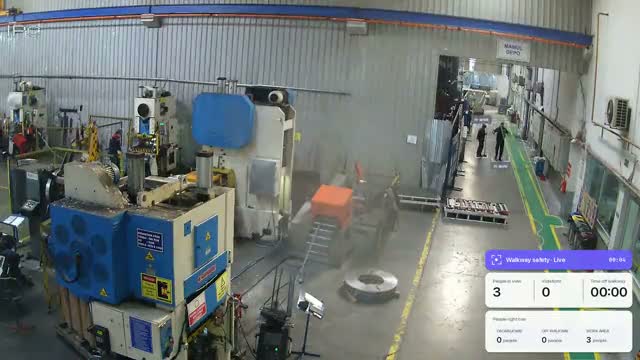
Real footage from systems we have built and deployed: safety, counting, crowd flow and more, each running on ordinary cameras.
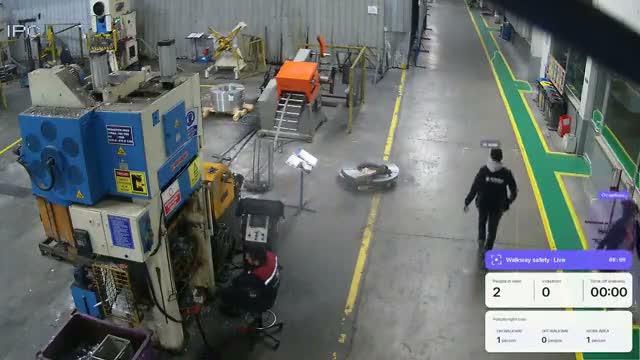 Walkway safety
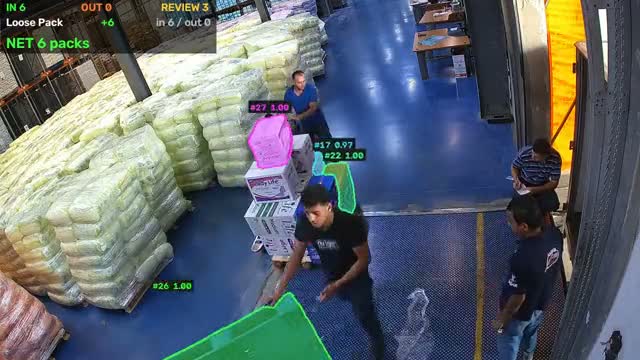
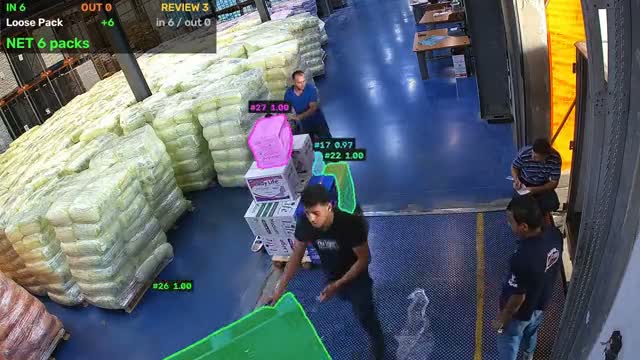 Loading-bay counting
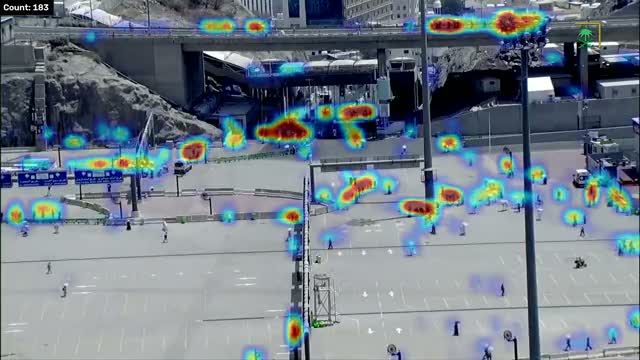
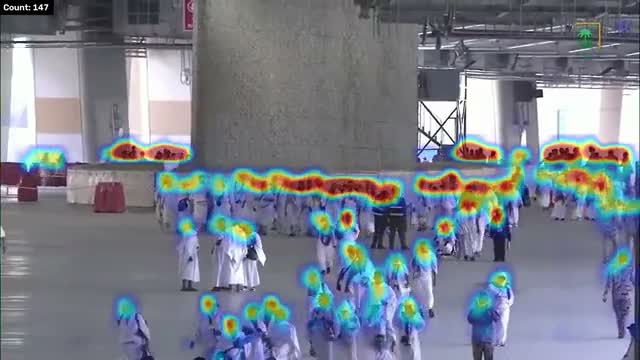 Crowd heatmaps
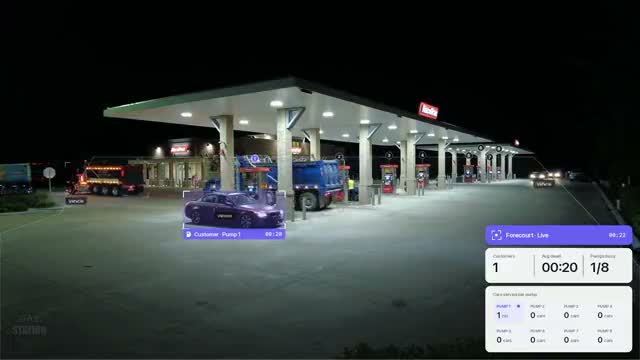 Forecourt monitoring
Solutions
Each one runs as a module on IFA, on the cameras you already have. Pick one to see what it does.
Net counts of packs, cartons, and pallets at loading bays and lines. Two synced cameras, an auditable ledger, a review queue.
ANPR for gates and parking — plate reading, occupancy, and access lists on edge hardware.
Queue length at counters, gates, and desks from existing cameras, with alerts when lines build up.
Intrusion, loitering, and restricted-area detection on your existing CCTV — alerts in seconds, video stays on site.
Pass/fail quality checks on production lines — labels, caps, and fill, decided next to your cameras.
Our edge computer vision platform. Solutions run on it as modules, for any industry.
How we work
From site inspection to deployment. We handle the entire pipeline.
Deployment
We offer different deployment options, tailored to your needs and infrastructure.
Runs on a server inside your own building. Video never leaves your network.
A small computer beside the camera. Results in milliseconds, and only events leave the site.
Cloud GPUs take on heavy jobs and scale across many sites.
Mix and match: edge where speed matters, on-premise where video must stay inside, cloud for the heavy jobs.
Bring your own cloud. We deploy inside your own cloud account, so data, access and billing stay under your control.
Workflows
IFA is our modular video AI platform. Each computer vision solution plugs into IFA and sends it events. You build workflows that turn those events into actions.
Analytics
Use the events your computer vision solutions send to build anything from simple counts to complex analytics.
People counted
86,928
Research/ Distillation
We distilled Qwen3-VL-8B into a small model fine-tuned for a computer vision task. It matches the 8B model's accuracy and returns each answer in about 16 ms.
Latency per video window, batch 1, one A100